
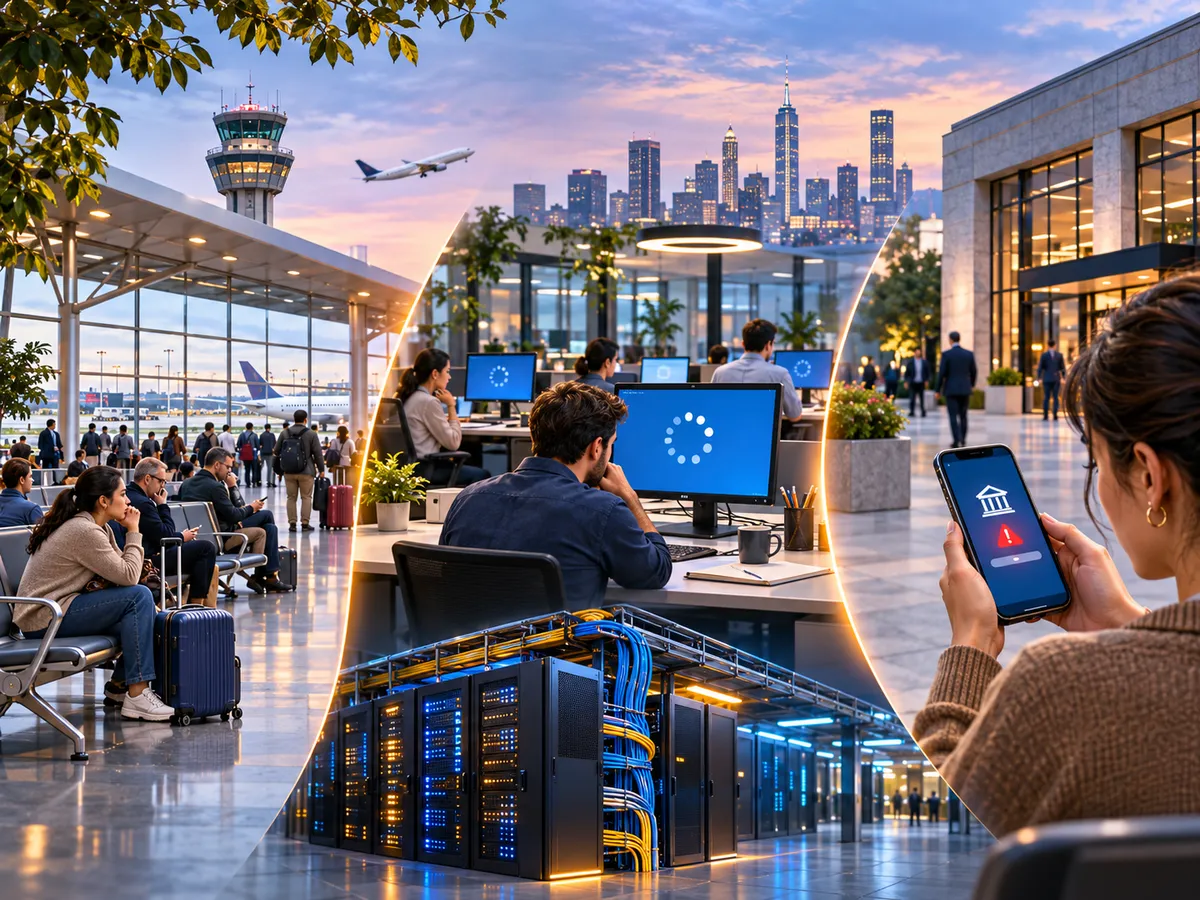

For many Americans, the past several days have brought an unsettling sequence of everyday services suddenly becoming unavailable. Flights were grounded, work emails stopped arriving, and banking customers struggled to access accounts or complete payments.
The problems occurred across different industries, but they exposed similar weaknesses in the systems Americans use every day. As DealInNow.com continues covering these disruptions, one question has become increasingly relevant: Why can a relatively small technical failure cause such widespread disruption?
The latest evidence does not point to a single cyberattack connecting these incidents. Instead, separate technical problems exposed vulnerabilities in aging equipment, software infrastructure and the complex networks connecting businesses and customers.
Technology Outages: What Happened Across the United States?
Three major incidents occurred between November 12 and November 16, affecting services used by millions of people and organizations.
| Date | Affected service | Reported problem |
|---|---|---|
| November 12 | Microsoft 365 | Software and infrastructure failures disrupted Outlook, Teams and connected services |
| November 13 | FAA | Telecommunications instability triggered a nationwide flight ground stop |
| November 16 | JPMorgan Chase | A software bug disrupted banking transactions and affected payments involving other financial institutions |
The incidents happened close together, but authorities and companies have not identified a common technical cause.
United Airlines also experienced a separate internal system outage on November 16 that delayed departures. The airline subsequently reported resolving the problem.
Together, the incidents demonstrated how many essential activities now depend on software and communications infrastructure that most customers never see.
FAA Ground Stop: How One Network Problem Disrupted U.S. Air Travel
On Friday, November 13, the Federal Aviation Administration ordered a nationwide ground stop after communications and radar information became unstable.
The restrictions prevented departing aircraft from taking off while controllers and technical teams worked to determine whether air traffic could continue safely.
The problem emerged during telecommunications maintenance involving L3Harris Technologies, a longtime FAA contractor.
According to the U.S. Department of Transportation’s official November 14 briefing, work was underway to replace an older copper communications connection with fiber-optic technology.
Transportation Secretary Sean Duffy said a router associated with that work began overwhelming other routers with repeated connection attempts.
Officials reported more than 1,000 connection attempts every four to five seconds, contributing to communication problems and interruptions affecting radar information.
The FAA restricted departures as a safety precaution. The ground stop was lifted Friday evening, but thousands of cancellations and delays continued over the weekend.
Investigators were still determining whether the failure involved installation work, defective equipment or another technical problem.
Why the FAA Incident Matters
Aviation depends on a national network of interconnected systems. Air traffic controllers need dependable communications and accurate aircraft information to manage flights safely.
When an important part of that network becomes unreliable, the safest response may be to temporarily restrict operations.
The FAA incident also raised questions about how older infrastructure can be upgraded without introducing new risks.
Modernization is necessary, but replacing legacy systems requires careful testing, monitoring and procedures for recovering from unexpected failures.
Microsoft Outage: A Months-Old Bug Triggered a Global Failure
The Microsoft disruption began on Thursday, November 12, affecting Outlook, Exchange Online, Teams, Copilot and other Microsoft 365 services.
Businesses lost access to important communication tools, while schools, government agencies and other organizations experienced operational difficulties.
Microsoft restored affected services and later released more information about the cause.
According to BleepingComputer’s analysis of Microsoft’s preliminary incident report, the problem involved three overlapping conditions:
- A software defect introduced months earlier, in July.
- Increased traffic after Microsoft Teams shifted onto another networking gateway.
- Reduced server capacity caused by a separate infrastructure issue.
Each condition created additional pressure on the system.
Together, they caused servers to become overwhelmed and stop responding.
When Microsoft attempted to redirect traffic to other servers, the additional demand contributed to further failures.
The problem spread across regions, illustrating how automated systems designed to maintain availability can sometimes struggle during an unusually severe outage.
Microsoft said it had restored services by Saturday, November 14. Its preliminary findings did not identify malicious activity as the cause.
For additional background on the initial service interruptions, see DealInNow’s Microsoft Outlook outage coverage.
Why the Microsoft Outage Spread So Widely
Microsoft 365 is used by businesses, hospitals, schools and government agencies worldwide.
Many organizations rely on several Microsoft applications simultaneously.
When the shared infrastructure supporting those applications fails, problems can affect email, scheduling, authentication and access to business information.
That concentration makes technology convenient and efficient during normal operations.
It also means that a failure at one major service provider can create difficulties for a large number of unrelated organizations.
Banking Disruptions: What Happened at Chase and Other U.S. Banks?
On Monday, November 16, thousands of customers reported difficulty accessing online banking services and completing transactions.
JPMorgan Chase was at the center of the disruption.
According to the Associated Press report on the banking outage, Chase attributed the problem to a software bug involving an on-premises hardware system.
The bank said the incident was not cyber-related.
Customers reported problems involving online banking, mobile applications and payments.
Other financial institutions also appeared on outage-monitoring services, including Wells Fargo, Bank of America, U.S. Bank, Capital One and Truist.
However, that does not mean every institution experienced the same internal technical failure.
Some problems involved transactions connected to Chase rather than a breakdown of another bank’s core systems.
Chase said its customers continued to have access to their accounts and funds, although certain transactions were taking longer than usual.
The bank also emphasized that the problem was not a financial-system-wide failure.
By early Tuesday, November 17, CBS News reported that outage-monitoring data indicated service had largely returned to normal.
Why Were Zelle Payments Affected?
The disruption also created problems for some customers attempting to send or receive payments through Zelle.
Zelle connects participating banks and credit unions, allowing customers to move money between eligible accounts.
A problem at one participating institution can interfere with transactions involving another institution.
During Monday’s disruption, some customers experienced delays because their transactions involved Chase.
A spokesperson for Zelle’s operator said the Zelle network itself remained operational.
That distinction demonstrates an important feature of modern financial systems: a payment can fail or be delayed even when the network carrying it is functioning normally.
The problem may instead exist at one of the financial institutions connected to the transaction.
Why Do Major Technology Systems Seem to Fail at the Same Time?
There is no verified evidence that the Microsoft, FAA and banking incidents were coordinated.
Still, the timing has made the interruptions feel connected.
Several broader factors help explain why these failures can become so disruptive.
1. Old Technology Still Supports Essential Services
Organizations rarely replace their entire technology infrastructure at once.
Instead, new equipment and software are introduced while older systems remain operational.
That approach allows businesses and government agencies to continue working, but it can create complications.
The FAA’s transition from copper communications lines to fiber-optic technology is one example.
A problem encountered during a relatively routine upgrade can have consequences far beyond the location where the work takes place.
2. Modern Systems Have More Dependencies
A mobile banking application is connected to much more than the screen a customer sees.
It may depend on transaction-processing systems, identity verification, internal databases and payment networks.
Similarly, cloud-based workplace applications depend on shared networking infrastructure.
A malfunction in one component can prevent several otherwise functional services from completing their tasks.
The more interconnected a system becomes, the more important it is to understand how failures can spread.
3. Recovery Systems Can Become Overwhelmed
Modern technology platforms often include automated recovery mechanisms.
When one server fails, traffic may be redirected to another.
When one connection becomes unavailable, systems may attempt to establish a different connection.
These measures usually improve reliability.
However, they can also create additional pressure if many components fail or large amounts of traffic arrive simultaneously.
Microsoft’s November outage illustrated that risk particularly clearly.
4. Americans Depend on a Small Number of Major Providers
A relatively small group of companies operates important portions of the nation’s digital infrastructure.
Microsoft supports workplace communications for numerous organizations. Major financial institutions process transactions involving customers at other banks. Specialized contractors operate equipment used by critical government systems.
When one of these providers encounters a serious problem, the effects can spread across many organizations.
That does not automatically mean the system is becoming less reliable overall, but it increases the potential impact of individual failures.
5. Failures Are More Visible Than Ever
An interrupted banking app, an unavailable email account or a delayed flight can become a national story within minutes.
Outage trackers and social media make it easier for customers to recognize that other people are experiencing the same problem.
This visibility can create the impression that technology failures are occurring more frequently.
However, determining whether outage frequency has actually increased would require consistent long-term data across comparable services. The recent incidents alone cannot establish that trend.
Were the FAA, Microsoft and Banking Failures Cyberattacks?
There is currently no confirmed evidence that the three disruptions resulted from a coordinated cyberattack.
Federal officials described the FAA problem as telecommunications instability.
Microsoft attributed its outage to software and infrastructure conditions.
Chase identified an internal software bug and said the problem was not cyber-related.
Cybersecurity specialists have also emphasized that major service interruptions do not always involve hackers.
As FOX6 Milwaukee reported, experts believe the recent incidents are likely unrelated and demonstrate the risks associated with increasingly complex technology.
A technical failure can be extremely disruptive without involving malicious activity.
That distinction matters because incorrectly labeling every major outage a cyberattack can create unnecessary panic and obscure the actual engineering problems that need to be addressed.
What Can Consumers Do When Essential Services Go Down?
Individuals cannot prevent an airline, bank or technology company from experiencing a system failure.
However, practical preparations can reduce the inconvenience.
For banking: Keep an alternative payment method available, check account activity through official channels and avoid repeatedly submitting a payment that may already be processing.
For travel: Enable airline notifications, verify departure information before leaving for the airport and keep travel documents accessible without relying entirely on internet connectivity.
For work: Maintain approved backup communication methods and save essential contact details in a secure location.
For account security: Be cautious about unexpected emails or text messages claiming to offer emergency access or outage fixes.
Criminals sometimes exploit public concern during service disruptions by sending fraudulent messages designed to steal account credentials.
Customers should use official websites or applications rather than links received through unsolicited messages.
What Should Businesses Learn From These Outages?
For businesses, the incidents provide a reason to review operational continuity rather than simply waiting for technology providers to improve their systems.
Organizations should understand which essential activities depend on particular vendors, cloud platforms or communications networks.
They should also consider what happens when a critical service becomes unavailable for several hours.
Possible safeguards include alternative communication channels, tested backup procedures, documented emergency responsibilities and regular reviews of external service dependencies.
Maintaining multiple systems does not eliminate every risk. Some backup arrangements may still depend on the same underlying provider or network.
The objective is to reduce the impact of a failure and restore operations safely.
Will More Widespread Outages Happen?
Technology companies and infrastructure operators continue upgrading their systems to improve performance, security and capacity.
Those improvements can reduce certain risks, but they also introduce new components and dependencies.
Experts warn that poorly managed changes, aging equipment and unexpected software interactions can still create large disruptions.
It is not possible to determine when the next major outage will occur.
What the past week demonstrates is that system reliability involves more than preventing individual components from breaking.
It also requires preventing one failure from spreading, maintaining essential services during disruptions and recovering without overwhelming the remaining infrastructure.
The Bottom Line
The FAA ground stop, Microsoft outage and banking disruptions were separate incidents with different reported technical causes.
Their timing made them appear connected, but no common cyberattack has been established.
The more important connection is structural. Modern life depends on complex systems that must remain reliable even when equipment fails, software behaves unexpectedly or a routine upgrade causes problems.
For consumers, sensible preparation can reduce disruption. For companies and government agencies, the challenge is building systems that remain dependable when something goes wrong.
The latest incidents show that restoring service is only part of the job. Preventing the next cascading failure may be the more difficult task.