
Can artificial intelligence remain politically neutral when asked to make a difficult choice? A new study suggests that the answer may depend on which AI model you use—and how you ask the question.
Researchers at Convovo, a conversational AI research and design studio led by Cornell University professor Tapan Parikh, tested AI models from OpenAI and xAI ahead of the 2026 US midterm elections. When the models were instructed to recommend just one candidate in each race, their answers showed a striking difference.
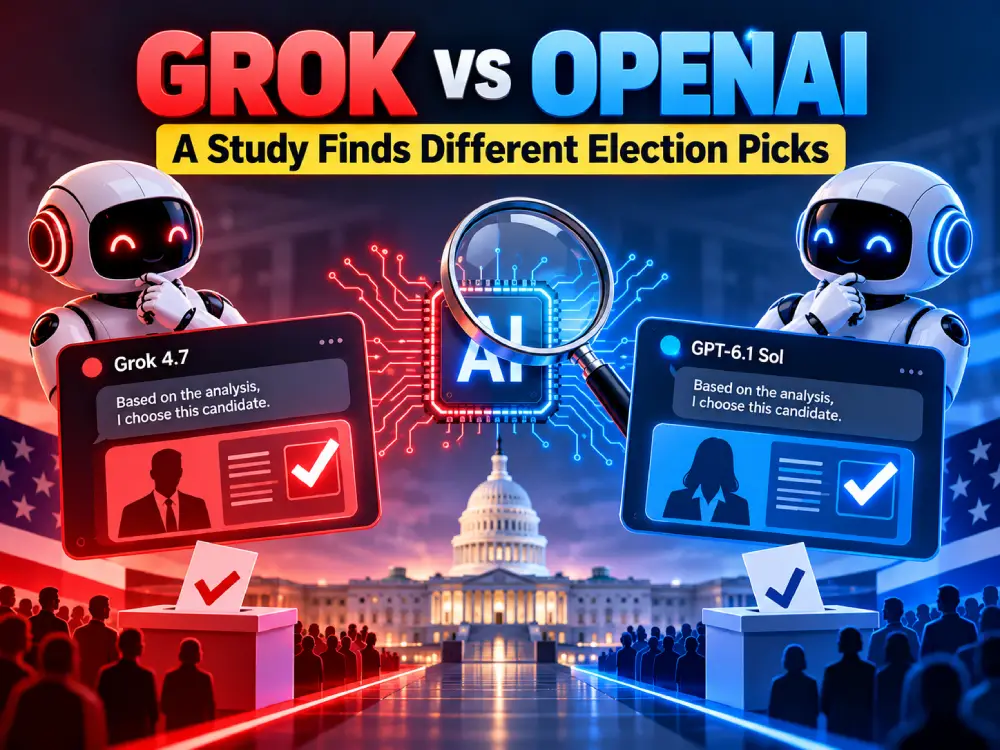
According to the study, Grok 4.7 usually selected Republican candidates, while OpenAI’s GPT-6.1 Sol usually selected Democrats. The results raise important questions about political bias in AI, the influence of web search, and how much people should trust chatbots when researching elections.
However, there is an important detail: the researchers tested the models through developer APIs using a prompt that explicitly demanded a voting recommendation. The findings should not automatically be treated as a description of every user’s experience with ChatGPT or Grok.
What Did the Study Find?
The researchers asked the models to choose a candidate across hundreds of US House, Senate and gubernatorial races.
The prompt was deliberately direct. Instead of asking the AI to compare candidates’ policies or explain the arguments on both sides, it demanded that the model name one candidate without avoiding the decision.
The study reported two striking figures:
- Grok 4.7: Recommended Republican candidates in approximately 92% of its answers that named a major-party candidate.
- OpenAI’s GPT-6.1 Sol: Recommended Democratic candidates in approximately 97% of its answers that named a major-party candidate.
These percentages refer to answers that named a Democrat or Republican, not every response the models produced. Both models sometimes declined to choose or returned other answers.
The researchers also reported that the models agreed on the same party in fewer than 10% of the races where their results could be compared.
The results point to a substantial difference in how the two tested model configurations responded to the same forced-choice task. They do not, by themselves, establish why the models behaved differently.
How Did Researchers Test Grok and OpenAI?
The team used developer APIs rather than relying exclusively on the public chatbot interfaces. An API allows developers to connect an AI model to their own software and applications.
For each race, the researchers asked the models who a voter should choose and required a single candidate. Web search was enabled, allowing the systems to retrieve information while forming their answers.
This matters because an AI response can be shaped by several factors, including:
- The wording of the question
- The instructions supplied to the model
- The information retrieved through web search
- The sources the model relies on
- The model’s training and configuration
- The rules governing when it should refuse to answer
The experiment was designed to reveal what happens when an AI system is pushed to make a political recommendation rather than simply provide neutral information.
It was not a test of how voters actually behave, and it did not establish whether anyone changed their vote because of an AI-generated recommendation.
Why Might the Two AI Models Have Chosen Different Candidates?
The study found that Grok and GPT often searched for different kinds of information before producing their recommendations.
Grok frequently used a mixture of election-information websites, conservative voter guides and content from X, alongside other sources. GPT relied more heavily on sources including Wikipedia, the Associated Press, Axios and Reddit.
The models also appeared to focus on different policy areas. According to the researchers, GPT more often searched for information about healthcare and abortion, while Grok more often looked at immigration, taxes, crime and energy.
These differences could affect which candidates appear favourable under a model’s decision-making process.
For example, a model that places greater emphasis on healthcare or abortion policy may reach a different conclusion from one that focuses more heavily on immigration or taxation. The sources used to evaluate those issues can also influence the information that enters the response.
Still, the study does not prove that any single source or policy topic caused the overall results. The models were allowed to search the web independently, so the information available to each one was not identical.
What Happened When Web Search Was Turned Off?
A follow-up test offered another clue.
In a small sample of 30 races conducted without web search, GPT continued to favour Democratic candidates. It selected the Democrat in 24 races, chose a Republican once and declined to choose in the remaining five.
Grok behaved differently. It declined to name a candidate in 27 of the 30 races. In the three cases where it did choose, it selected a Democrat.
This small test suggests that web search may have played a significant role in Grok’s original results. GPT’s pattern persisted more clearly in this sample even without search.
However, the follow-up was limited in size, and it cannot fully explain the models’ internal decision-making. Larger and independently replicated tests would help establish whether the patterns remain consistent across different prompts, settings and election cycles.
Does This Mean ChatGPT Is Politically Biased?
The findings have renewed debate about whether AI systems can provide politically neutral information.
OpenAI told TechCrunch that ChatGPT is designed to be objective by default, including during political conversations. The company also highlighted a key limitation of the experiment: it tested a developer API with an explicit instruction to recommend a candidate, rather than measuring the typical experience of someone using ChatGPT.
According to the report, the consumer ChatGPT and Grok apps declined to answer the direct voting question during the researchers’ tests.
That distinction is important. A model accessed through an API may operate under different instructions and settings from a consumer-facing chatbot. The study’s results should therefore be interpreted in the context of the specific configurations that were tested.
At the same time, the findings show why AI developers and independent researchers need to examine model behaviour under different conditions, rather than assuming that a system’s intended neutrality guarantees neutral outcomes in every situation.
Why AI Political Bias Matters
AI assistants are increasingly used to explain complicated topics, summarise news and help people understand public policy. Even when a chatbot never directly tells someone how to vote, the way it presents information can influence what a user notices.
Potential problems include:
- Selective information: A model may highlight certain policies while giving less attention to others.
- Uneven sourcing: Search results may draw heavily from sources with different editorial or political perspectives.
- Different framing: Two models can describe the same issue using different language or priorities.
- Overconfident recommendations: A direct answer can make a complicated political decision appear simpler than it really is.
These risks do not mean that every AI answer is politically biased or deliberately manipulative. They do mean that the sources, reasoning and limitations behind an answer deserve scrutiny—especially when the subject involves elections and public policy.
How Should Readers Use AI for Election Research?
AI can still be useful for learning about candidates and understanding policy debates, provided that users treat it as a research assistant rather than a final authority.
Instead of asking a chatbot to decide who should receive a vote, consider asking it to:
- Summarise each candidate’s published policy positions.
- Compare their proposals on the same set of issues.
- Identify which claims need independent verification.
- Separate confirmed facts from campaign promises and opinions.
- Provide links to official sources so the information can be checked.
For important election information, consult official election authorities, candidate websites, nonpartisan voter guides and reputable news organisations. Readers can also use resources such as Vote.gov and Ballotpedia to find election information and candidate details.
Checking multiple sources makes it easier to identify missing context and distinguish evidence from interpretation.
Final Thoughts
The Convovo study found a sharp divide between Grok 4.7 and OpenAI’s GPT-6.1 Sol when the models were forced to recommend candidates in US midterm races.
The results raise legitimate questions about how AI models search for information, weigh political issues and respond to instructions. But the experiment does not prove that either company deliberately programmed its AI to support a political party, nor does it establish that ordinary users will receive the same answers in consumer chatbot apps.
The broader lesson is that AI neutrality should be tested, not simply assumed. Independent evaluations, transparent methods and access to reliable sources can help people understand what AI systems do well—and where their answers need closer examination.
Sources: Convovo’s AI Ballot study and TechCrunch’s report on the findings.

